HAS-RL: Clinician-Configured Force Safety in Robotic Ultrasound (BSc Thesis)
HAS-RL: Human-Adaptive Safe Reinforcement Learning
Clinician-Configured Force Safety in Robotic Ultrasound Spinal Scanning
Bachelor of Science Thesis in Computer Science · Amirkabir University of Technology (Tehran Polytechnic)
Mohammad Hadi Niknam
Overview / نگاه کلی
Abstract
Robotic ultrasound (US) imaging promises to standardize diagnostic scanning and alleviate sonographer fatigue. However, any robotic manipulator operating in direct physical contact with human anatomy must rigorously respect hard force-safety limits that vary across patients, tissue types, and clinician preferences. Prior safe reinforcement learning (RL) methods in robotic ultrasound train policies against a single, static force threshold; any change in tolerated force requires expensive retraining from scratch. Furthermore, recent multi-armed bandit multiplier methods designed for offline RL introduce destabilizing non-stationarity when transplanted into online policy-gradient loops.
We introduce HAS-RL (Human-Adaptive Safe Reinforcement Learning), a framework delivering: (i) Operator-Conditioned Zero-Shot Safety where the runtime safety ceiling κ is an observation state feature, tracking mid-scan dial adjustments without retraining or violations; (ii) Smoothed Bandit-Lagrangian (SBL) which applies an exponential moving average to EXP3 multiplier expectations to stabilize online learning; (iii) Anticipatory Trajectory Tracking cutting RMS tracking error by 28%; and (iv) Two-Sided Acoustic-Window Safety [κlow, κhigh] matching acoustic coupling physics.
چکیده پایاننامه
تصویربرداری اولتراسوند رباتیک راهکاری نویدبخش برای استانداردسازی اسکنهای تشخیصی و کاهش خستگی سونوگرافر است؛ با این حال، سامانههای رباتیک کمکی به دلیل تماس فیزیکی مستقیم با بدن بیمار، ملزم به رعایت قیود سختگیرانه برای فشار ایمن هستند؛ مقداری که بسته به نوع بافت، شرایط بالینی و ترجیح پزشک تغییر میکند. روشهای پیشین یادگیری تقویتی ایمن در اولتراسوند رباتیک، یک policy را بر اساس یک آستانه نیروی ثابت آموزش میدهند؛ از این رو با هر تغییر در حد مجاز، کل فرایند آموزش باید از ابتدا تکرار شود.
در این پایاننامه، چارچوب HAS-RL با چهار نوآوری اصلی معرفی میشود: ۱. تنظیم آنلاین فشار ایمنی به صورت زیروشات: سقف مجاز مستقیماً در بردار مشاهده قرار گرفته و مدل بدون نیاز به بازآموزی، تغییر آنلاین پیچ تنظیم فشار در حین اسکن را دنبال میکند؛ ۲. سازوکار لاگرانژ باندیتی هموارشده (SBL): پایدارسازی متغیر دوگان باندیتی با میانگین متحرک نمایی؛ ۳. رهگیری مسیر پیشبین: کاهش ۲۸ درصدی خطای رهگیری؛ ۴. ایمنی پنجره آکوستیک دوطرفه: مدلسازی پنجره بالینی [κlow, κhigh].
System Architecture / ساختار سیستم
The HAS-RL control pipeline bridges clinician inputs, reinforcement learning decision-making, and robotic compliance control.
Core Innovations / نوآوریهای کلیدی
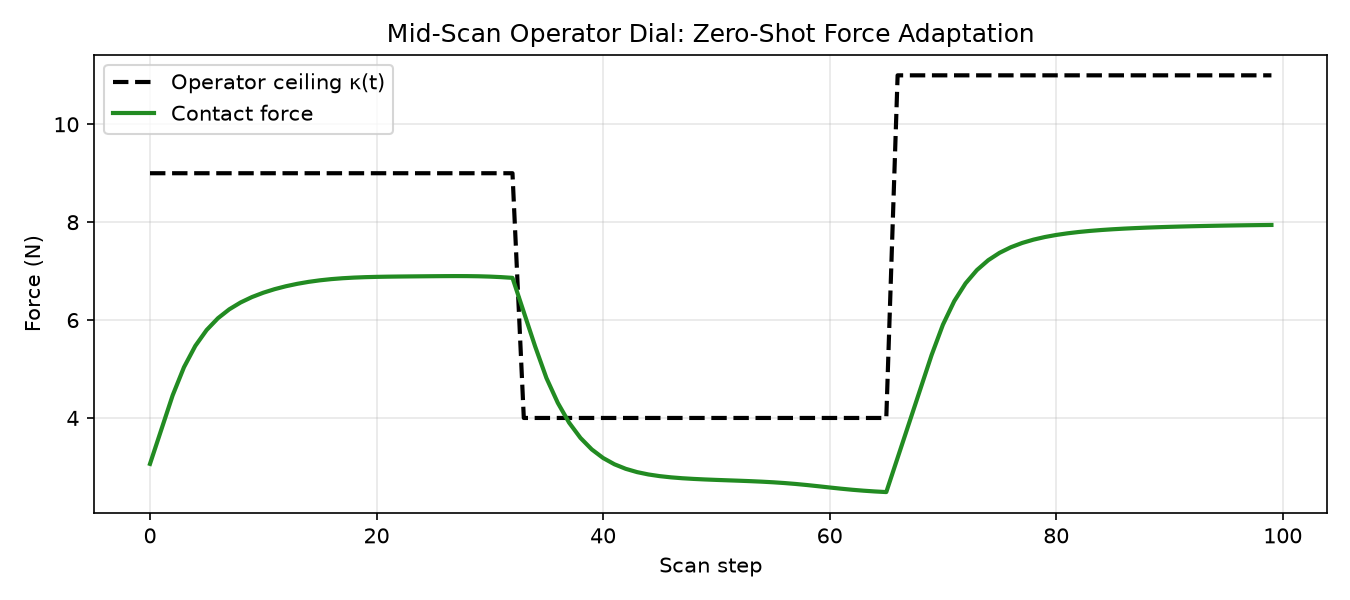
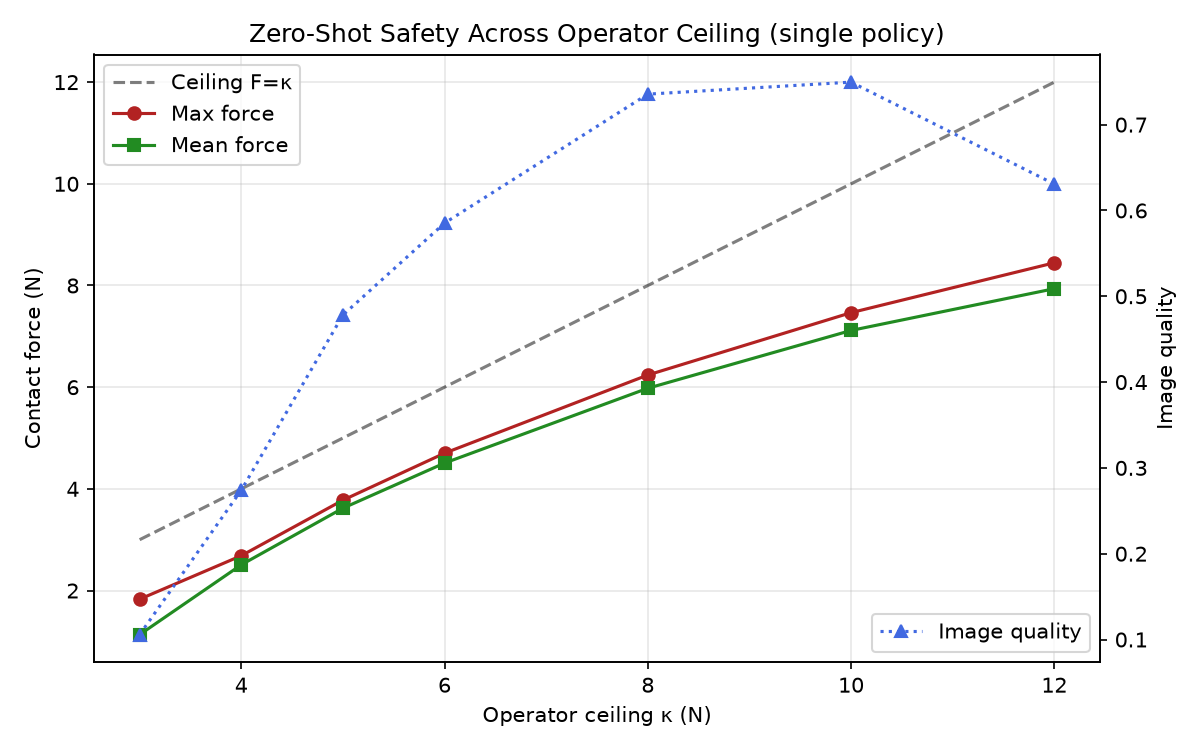
1. Operator-Conditioned Zero-Shot Safety / تنظیم آنلاین فشار زیروشات
Instead of baking a fixed $F_{\max}$ into policy weights, HAS-RL treats the clinician’s runtime safety setting as an observation variable: \(s_t = \left[x_t, y_t, F_t, e_t, \kappa_t\right]\)
The clinician can freely dial the force limit during an active scan. The policy reacts in real time, modulating contact force without a single constraint breach.
2. Smoothed Bandit-Lagrangian (SBL) / سازوکار لاگرانژ باندیتی هموارشده
To combine the bounded penalty guarantees of multi-armed bandit multiplier selection (EXP3) with online policy-gradient learning, SBL maintains an exponential moving average over expected multiplier weights: \(\bar{\lambda}_k = (1 - \tau)\bar{\lambda}_{k-1} + \tau \mathbb{E}_{a \sim p_k}[\lambda_a]\)
This resolves the gradient variance and policy collapse caused by raw bandit arm sampling while maintaining zero constraint violations.
3. Two-Sided Acoustic-Window Safety / پنجره ایمنی آکوستیک دوطرفه
Ultrasound imaging requires minimum contact to establish acoustic coupling, while excessive force injures soft tissue. HAS-RL enforces: \(\kappa_{\text{low}} \le F_{\text{contact}} \le \kappa_{\text{high}}\)
This eliminates the “headroom gap” of ceiling-only safety, reaching 10.2 N in $[9, 12]\,\text{N}$ windows versus 7.97 N under naive ceiling constraints.
Quantitative Evaluation / نتایج تجربی
Safety Performance Comparison ($\kappa = 5\,\text{N}$)
| Method | Mean Contact Force | Max Force | Image Quality | Violations | Safety Status |
|---|---|---|---|---|---|
| Vanilla PPO (Baseline) | 5.23 N | 5.48 N | 0.90 | 95 | Failed |
| HAS-RL (Ours) | 3.62 N | 3.77 N | 0.47 | 0 | 100% Compliant |
Multiplier-Mode Stability Ablation (3 Random Seeds)
| Mode | Mean Image Quality | Train Violation Std ($\sigma_V$) | Multiplier Std ($\sigma_\lambda$) |
|---|---|---|---|
| PPO-Lagrangian (Dual Ascent) | 0.576 | 16.66 | 0.29 |
| EXP3 Raw Bandit | 0.492 | 13.51 | 1.43 |
| Smoothed Bandit-Lagrangian (SBL - Ours) | 0.603 | 11.99 | 0.42 |
Two-Sided Operator Window Performance
| Clinician Window | Mean Force | In-Window Residence | Violations | Image Quality |
|---|---|---|---|---|
| $[2.5, 4.0]\,\text{N}$ | 3.26 N | 100% | 0 | 0.67 |
| $[5.0, 8.0]\,\text{N}$ | 6.50 N | 100% | 0 | 0.99 |
| $[9.0, 12.0]\,\text{N}$ | 10.22 N | 100% | 0 | 0.74 |
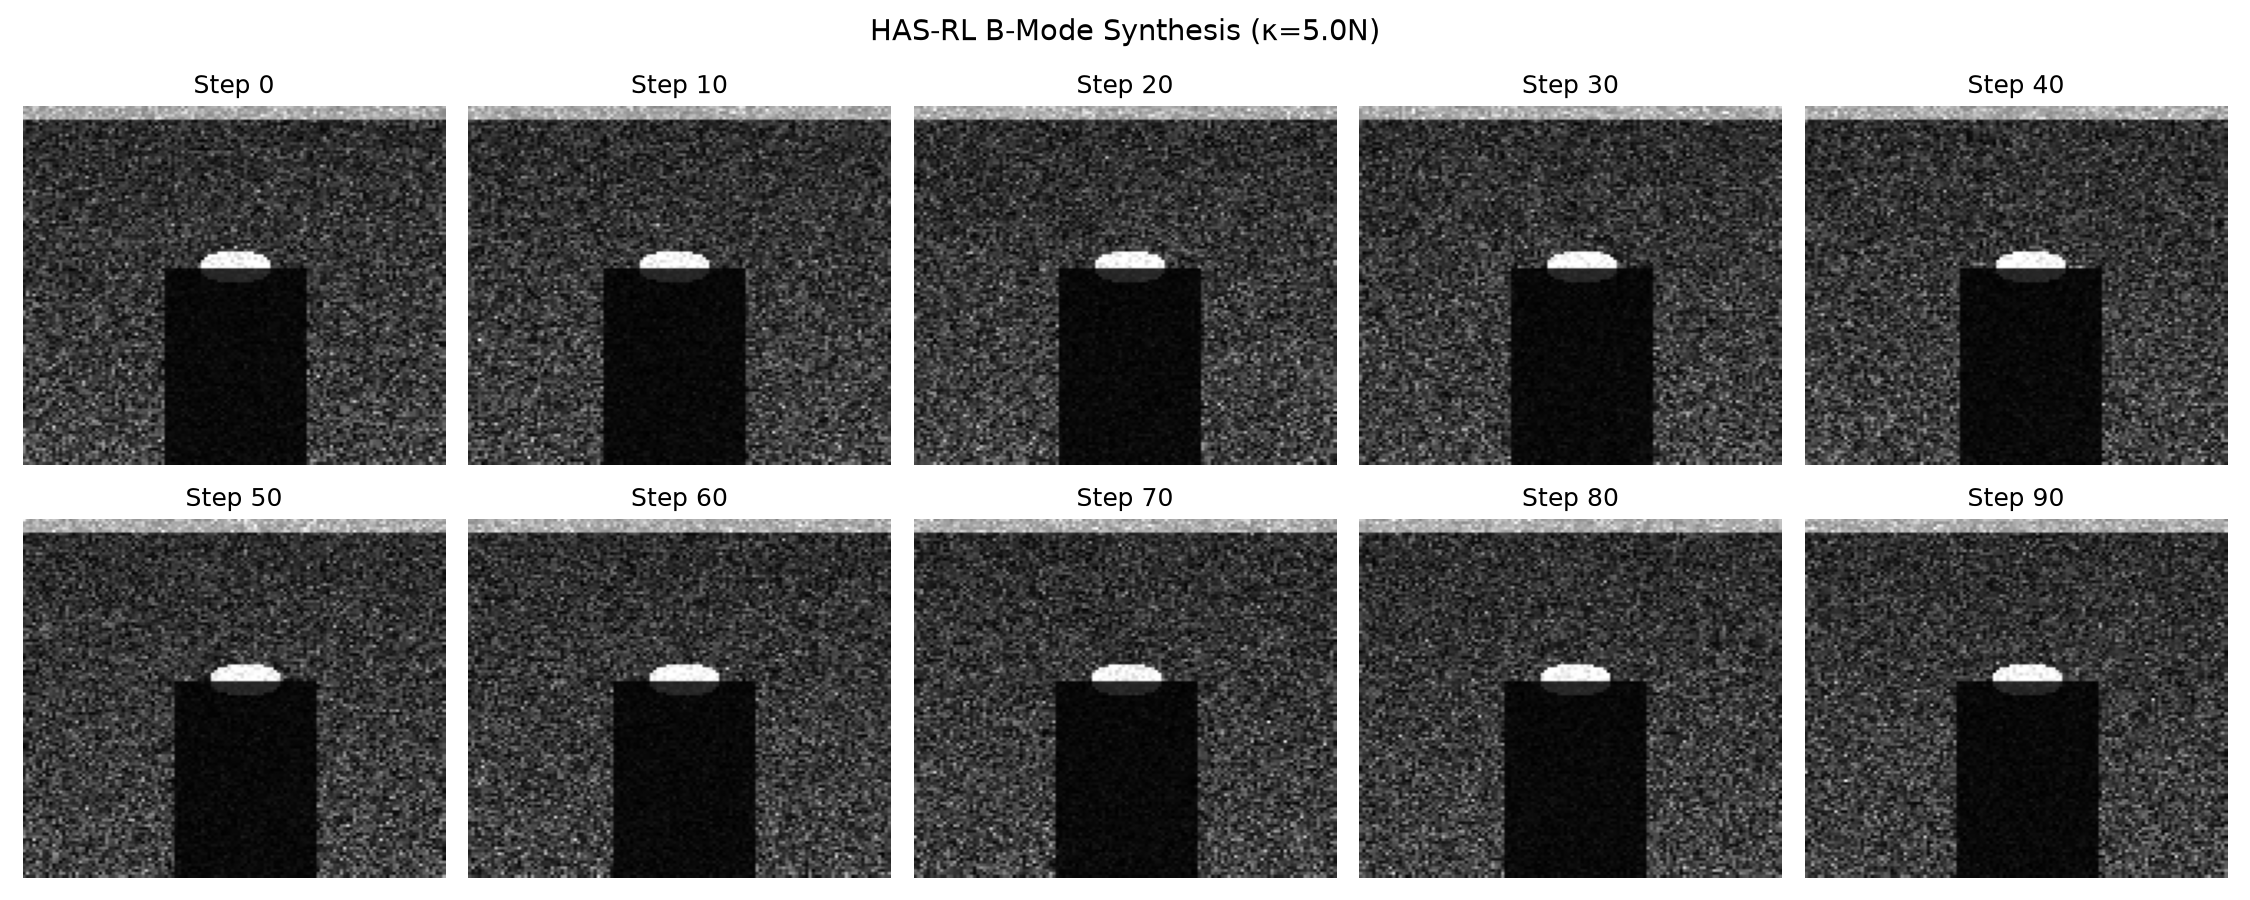
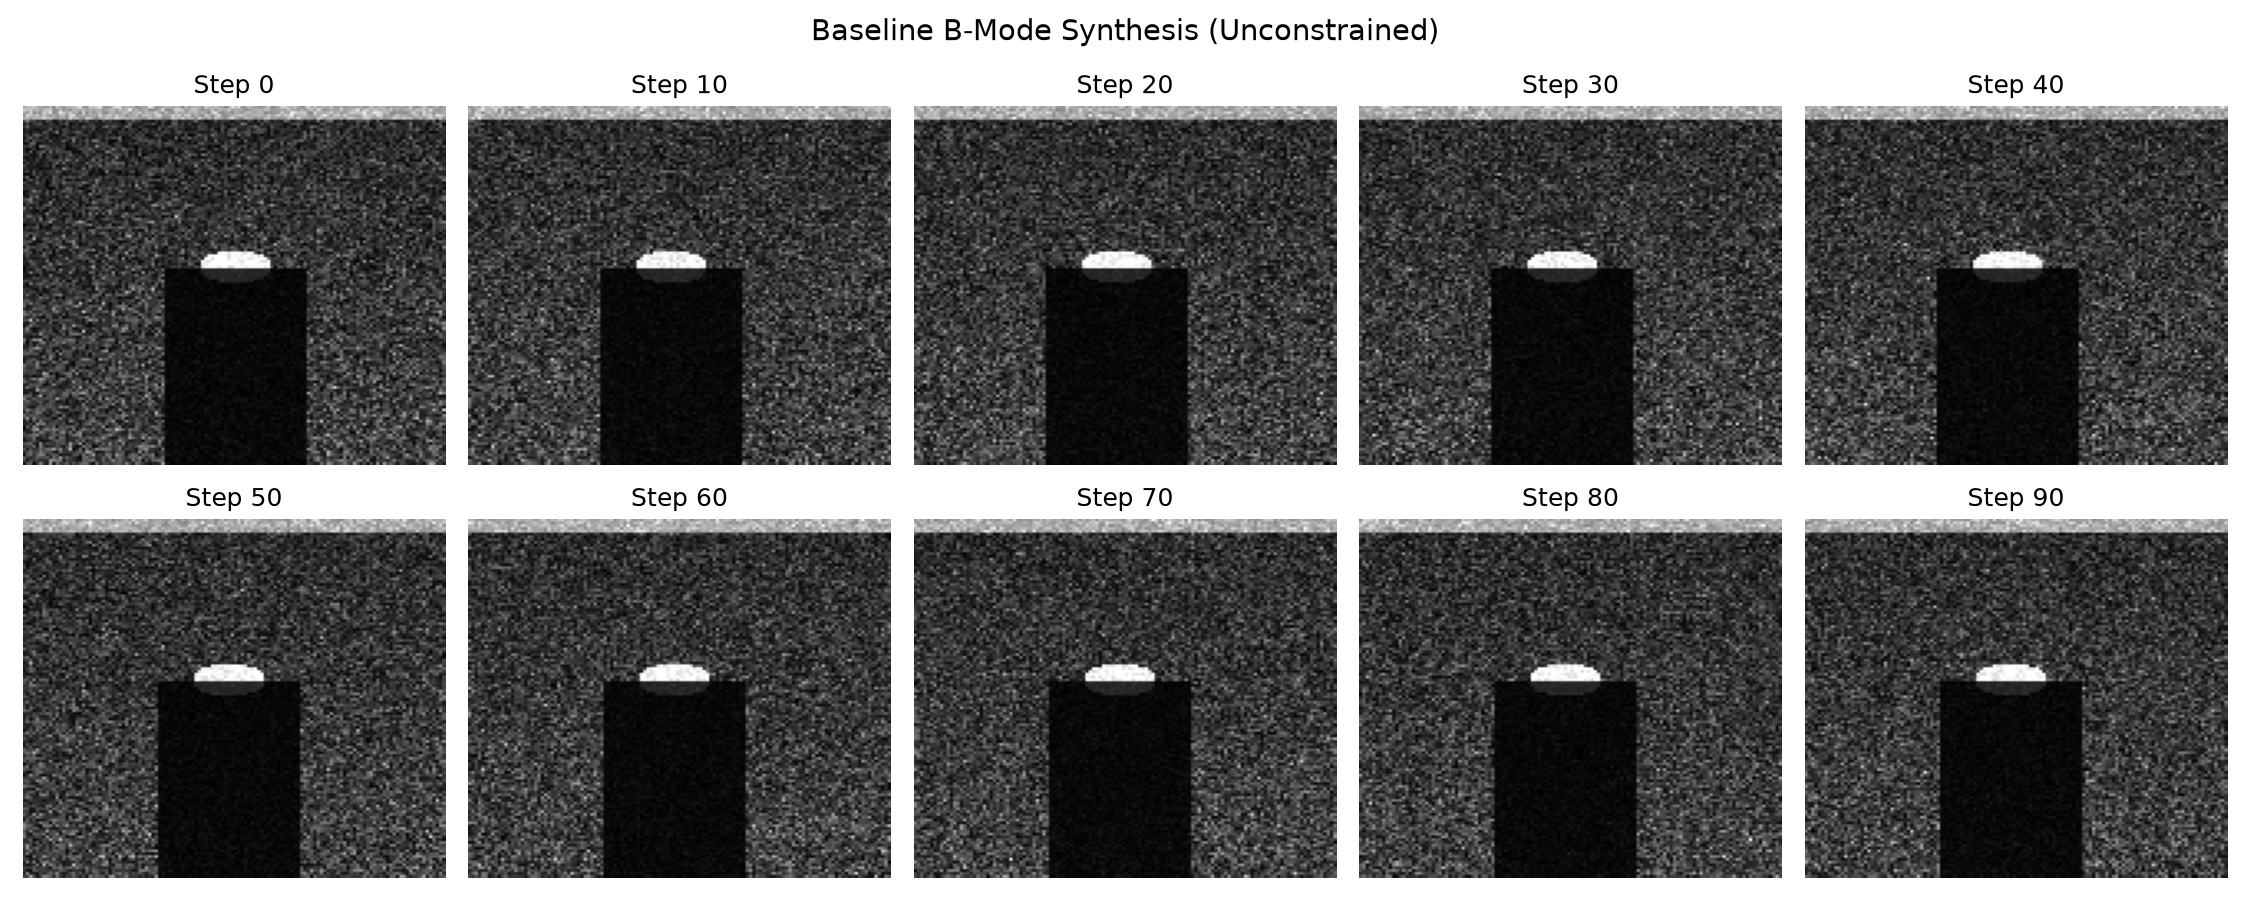
Ultrasound B-Mode Image Reconstruction
Amirkabir University of Technology Defense Details / جزئیات دفاع
- عنوان پایاننامه: یادگیری تقویتی ایمن با تنظیم نیروی اپراتور در اسکن رباتیک اولتراسوند ستون فقرات
- دانشگاه: دانشگاه صنعتی امیرکبیر (پلیتکنیک تهران) - دانشکده ریاضی و علوم کامپیوتر
- مقطع و رشته: کارشناسی علوم کامپیوتر
- نگارش: محمدهادی نیکنام
- زمان دفاع: تابستان ۱۴۰۵
- تعداد صفحات: ۶۰ صفحه به همراه اثباتهای ریاضی و کدهای شبیهساز
Citation
@thesis{niknam2026hasrl,
  title        = {HAS-RL: Human-Adaptive Safe Reinforcement Learning for Clinician-Configured Force Safety in Robotic Ultrasound Spinal Scanning},
  author       = {Niknam, Mohammad Hadi},
  school       = {Amirkabir University of Technology (Tehran Polytechnic)},
  year         = {2026},
  type         = {Bachelor's Thesis},
  address      = {Tehran, Iran},
  url          = {https://mhadiniknam.github.io/blog/2026/has-rl-bachelor-thesis/}
}
Enjoy Reading This Article?
Here are some more articles you might like to read next: